Additive Feature Attribution Methods
"Additive Feature Attribution Methods" (AFAMs) are a class of extrinsic explainability methods (where the reference model's internals aren't analysed). This post explores a few of these methods.
What are AFAMs?
The Additive Feature Attribution Methods (AFAMs) class was identified in the paper A Unified Approach To Interpreting Model Predictions. The methods in this class approximate a prediction of the original model () with an explanation model () which is a linear addition of binary features, making it simpler and interpretable.
How do explanation models relate to out general idea of explanations? Here is what Explaining Explanations in AI says:
These [explanation] models can be understood as a "do it yourself kit" for explanations, allowing a practitioner to directly answer "what if questions" or generate contrastive explanations without external assistance.
Mathematically, the explanation model () is described as:
Each is an effects of a binary feature in the output. The different methods in the class estimate differently.
A Unified Approach To Interpreting Model Predictions defines Explanation Model as:
We introduce the perspective of viewing any explanation of a model's prediction as a model itself, which we term the explanation model." and also "Instead, we must use a simpler explanation model, which we define as any interpretable approximation of the original model.".
The paper Explaining Explanations in AI relates such models to approximate scientific models (which are all of them as reminded by Box's maxim "All models are wrong but some are useful"). So it is important for the recipients or users to know where models are reliable, where they break down or where they have unknown behaviour. In their words:
For an individual to be able to trust such a model as an approximation, they must know over which domain a model is reliable and accurate, where it breaks down, and where its behaviour is uncertain. If the recipient of a local approximation does not understand its limitations, at best it is not comprehensible, and at worst misleading.
This is not to say that local approximations are without merit, but rather that they can only reliably have explanatory power if their limitations are clearly documented and understood by recipients.
The paper also highlights a link between explanation models (and would also apply to transparent models) to contrastive and what-if explanations:
Over the domain for which the model accurately maps onto the phenomena we are interested in, it can be used to answer "what if" questions, for example "What would the outcome be if the data looked like this instead?" and to search for contrastive explanations, for example "How could I alter the data to get outcome X?"
However (as they note) local explanation models won't be accurate outside of the local domain (by definition). Also, the explanation models may be faithful to the prediction model, but if the latter is unreliable, the explanation model will also be (though on the positive side, this may be more obvious in the simpler model).
SHAP
Linear LIME, DeepLIFT and other methods calculate s differently, in turn yielding different coefficients.
The Unified Approach to Interpret Model Predictions proposes that models should have local accuracy, missingness, consistency which, they argue, lead to coefficients that are more intuitive for humans.
The terms are defined as:
- Local Accuracy: There must be equality when the input is the original one (), that is .
- Missingness: If the reference vector () has a "missing" component () then the feature must have no impact, that is .
- Consistency: if one of two models is larger just turning feature on and off, then it must have a larger .
This how they bring in a result from game-theory by Shapley, which they call Shapley values.
Their Theorem 1 guarantees that a linear explanation model plus the 3 requirements leave Shapley Values as the best (and unique) coefficients. Other methods violate some of these 3 properties (so the authors modify them to comply).
SHAP (SHapley Additive Explanations) Values are the Shapley Values of a conditional expectation function of the original model: (Section 4, see Figure 1). are non-zero indices.
- For example, with then . So the Shapley values are the change in the expected model prediction when conditioning on a feature.
Note
The most accurate Shapley Values are expensive to calculate. Approximations can be used in some cases to speed this up.
Approximating SHAP Values
The approximations can be model agnostic: Shapley Sampling Values, Quantitative Input Influence, Kernel SHAP; or they can be model-specific: Max SHAP, Deep SHAP.
The actual approximations are:
Approximation 1: Feature independence (implies non-multicollinearity).
- Shapley sampling values method,
- Quantitative Input Influence,
- Kernel SHAP (requires both assumptions).
Approximation 2, model linearity: Shapley regression values.
- SHAP provides both global (average across inputs) and local (for a given input).
Kernel SHAP
Can we modify Linear LIME's Loss function so that the values of coefficients found are Shapley values? Yes! These are also more intuitive to humans, and remove some of the heuristics (kernel selection and complexity metric) of it.
The Linear LIME quantities of proximity kernel (), complexity penalty () and Loss () are turned into a shapley kernel, , and the same weighted loss.
The SHAP values / coefficients for this linear model with assumed-uncorrelated features can be estimated by weighted linear regression.
This method is called Kernel SHAP, and it's fast to compute.
LIME and SP-LIME
The paper "Why Should I Trust You?": Explaining the Predictions of Any Classifier proposes the Local Interpretable Model-Agnostic eXplanation (LIME) and the Submodule Picking LIME.
LIME isn't a particular model but rather a set of characteristics that explainable methods should have, according to the authors (more on this later).
Let's first look at LIME as implemented in a concrete case.
Why would this be useful? A concrete example
A linear model with few-ish, interpretable features, locally fit to a complex one is in line with LIMEs' requirements.
Local fit means fitting only in the vicinity of the input of interest. The input features may differ from those in the original model.
The original paper shows an example comparing two different models that were fit by linear ones:
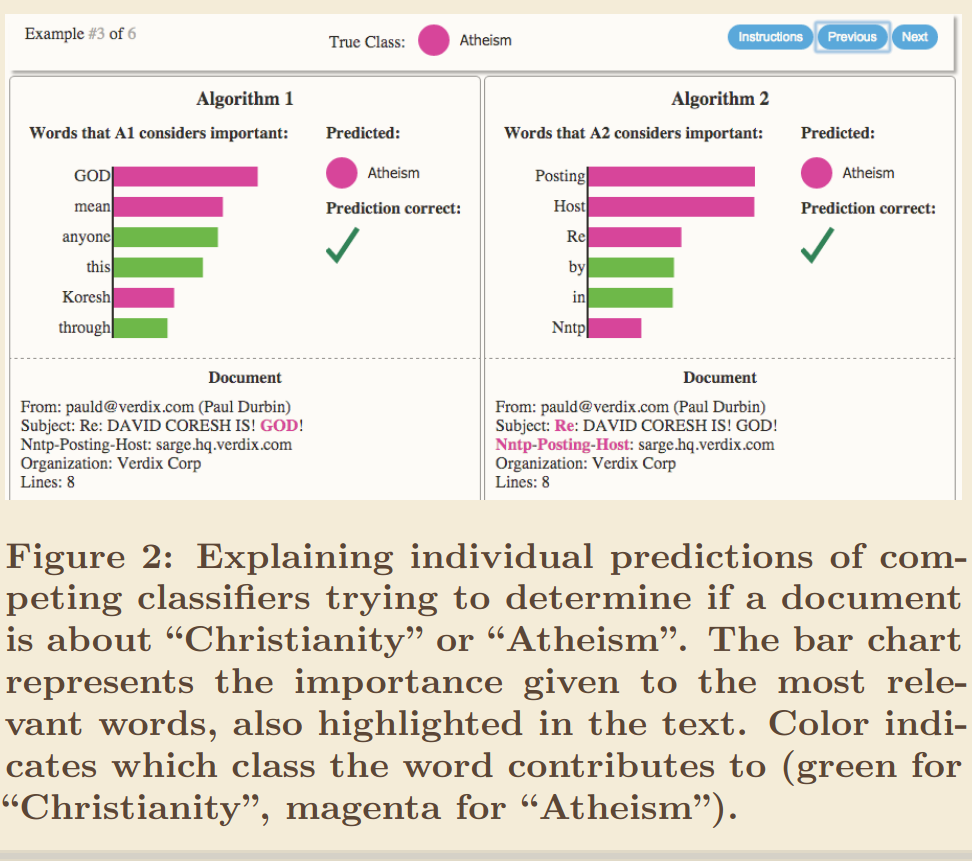
Image taken from paper.
The image makes clear some of the uses of it:
- The interpretable features, alongside their contributions (weights) to the prediction, can help decide whether to trust the prediction or not.
- Feature engineering such as removing features (or certain data) that the model uses but harm generalisation,
- Comparing models is easy (through the linear proxies). It's especially useful if the original models' accuracy (and other metrics) are similar, and their features non-interpretable.
- Here, one of them is untrustworhy (right hand side), giving high weight to meaningless features.
LIME / Desiderata
The authors consider 4 properties to be desirable in an explanation model:
- Local: the interpretable or explanation model approximates the original model in the vicinity of a particular prediction. In contrast, global explanations explain the full model.
- Model-agnostic: any model can in principle be explained by this method.
- Interpretable Explanation: In this paper, "interpretable" is a desired characteristic of "explanation", and provides qualititative understanding (a simple answer to "Why was this prediction made?"). In their own words:
An essential criterion for explanations is that they must be interpretable, i.e., provide qualitative understanding between the input variables and the response. We note that interpretability must take into account the user's limitations.
Additionally, they include 4. A global perspective, a mechanism to get a sense of the full model's behaviour.
The first 3 can be called LIME; the Submodule Picking LIME (SP-LIME), which selects LIME explanations to give a global explanation of the model.
LIME is a slightly more explicit version of the first 3 desired properties. Let's explore this.
-
Which specific representations does the LIME framework consider interpretable?
An example of an interpretable representation is a binary vector with components indicating presence / absence of a feature (e.g. a word) in the explanation model.
-
Which models does the LIME paper consider interpretable?
(...) interpretable models, such as linear models, decision trees, or falling rule lists [27], i.e. a model can be readily presented to the user with visual or textual artifacts.
-
Complexity is the opposite of interpretable, so the loss (we skip it here) to train the explainable model accounts for it, and gives local samples more importance than remote ones. Here being the model class of :
As not every may be simple enough to be interpretable thus we let be a measure of complexity (as opposed to interpretability) of the explanation .
The definition of complexity depends on . For linear models it may be the number of weights.
-
They also define a sampling procedure to create the training set. This is detailed in the concrete algorithm in the next section.
Linear LIME: An Algorithm
The paper implements LIME using the class of sparse linear models as explanation model, which we could call Linear LIME (as A Unified Approach to Interpreting Model Predictions does). Here is my interpretation of the algorithm (the primed variables denote binary vectors):
- A model and an input vector needs explaining,
- Start an interpretable, binary vector with only the dimensions of interest of (it may be all-ones often),
- Generate perturbed binary variants of called ,
- Use different to make variants of called .
- Written in [A Unified Approach to Interpreting Model Predictions][unified_approach_lcobf] paper as .
- Now we have training tuples .
- Use the dataset to fit the linear model using .
- To select interpretable features they apply -LASSO.
- LASSO is like a sparse linear regression, some coefficients are pushed to and correspond to variables we can ignore. How many are are pushed to may be controlled by the complexity penalty in the loss function.
- This is why the number of input features for the interpretable model (, ) may be much smaller than that of , .
- Then the non-zero variables are used to fit to but now using least-squares.
SP-LIME is defined as:
[SP-LIME] a global understanding of the model by explaining a set of individual instances.
The complex part of SP-LIME is selecting instances that add the maximum insight, and avoiding repeated ones. The algorithm is briefly described later on.
Linear LIME: A problem
Explaining Explanations in AI has both an interesting explanation and also criticism of LIME, so it is pasted below without changes:
The other option, and most influentially proposed by Ribeiro et al. (2016) in their Locally Interpretable Model-Agnostic Explanations (LIME) approach, is to binarize the problem. Rather than trying to fit a linear classifier to a large range of values, the authors consider a binary problem, where for each feature they attempt to switch it on and off, allowing them to answer the question “What is the contribution of feature f to the classifier response, given the data it currently sees?” This leaves open the question of “the contribution compared to what?” For unstructured data, such as a count of how many times particular words occur in a document, it makes sense to compare against a baseline created by setting the count to 0. For structured data this is more problematic. For example, how can we evaluate the importance of someone’s salary to a loan decision, if the classifier can only evaluate people with valid salaries? The answer is to compare it against a different valid salary, but it is unclear how this valid salary should be chosen.
Particularly it highlights that we are looking at rather than anything else (the can be meaningless, since that can be very far away from the value on ).
And here it matters to which state of each value maps to. It is also important that the corresponding vectors near ! Otherwise, the difference is meaningless, because one of them is likely inaccurate.
The last part of the paper explores which state should be which is can be actual or a reference value. As said above, the points must be near for best results.
There are many interesting caveats with LIME which are worth exploring in detail.
SP-LIME: The Algorithm
The goal here is picking the most informative instances, and without repetition.
A coverage metric is defined: .
Here, is a matrix of weights (columns) for each instance (row).
is the global importance of a component, defined as . The larger the sum of weights is, the more important.
A marginal coverage for each candidate instance () is performed, then the instance that increases of the most is appended to it.
Note
This approximates the with the largest coverage, but it's not exact because the total max could be one that does not max it on each step!
To increase the coverage at all, it must add some non-zero value to a column of zeros.
LIME: Final Comments
Explanation models do not replace but complement accuracy or other evaluation metrics.
Sources
- A value for n-person games (1952)
- "Why Should I Trust You?": Explaining the Predictions of Any Classifier (2016),
- A Unified Approach to Interpreting Model Predictions (2017),
- Explaining Explanations in AI (2019),
- Principles and practice of explainable machine-learning (2021, 25 pages): overview of many aspects of XAI,
- A Perspective on Explainable Artificial Intelligence Methods: SHAP and LIME (2025): conceptual aspects (weaknesses, strengths, assumptions) of the popular XAI methods SHAP and LIME.